Your agent makes YouTube thumbnails that read at 200 pixels.
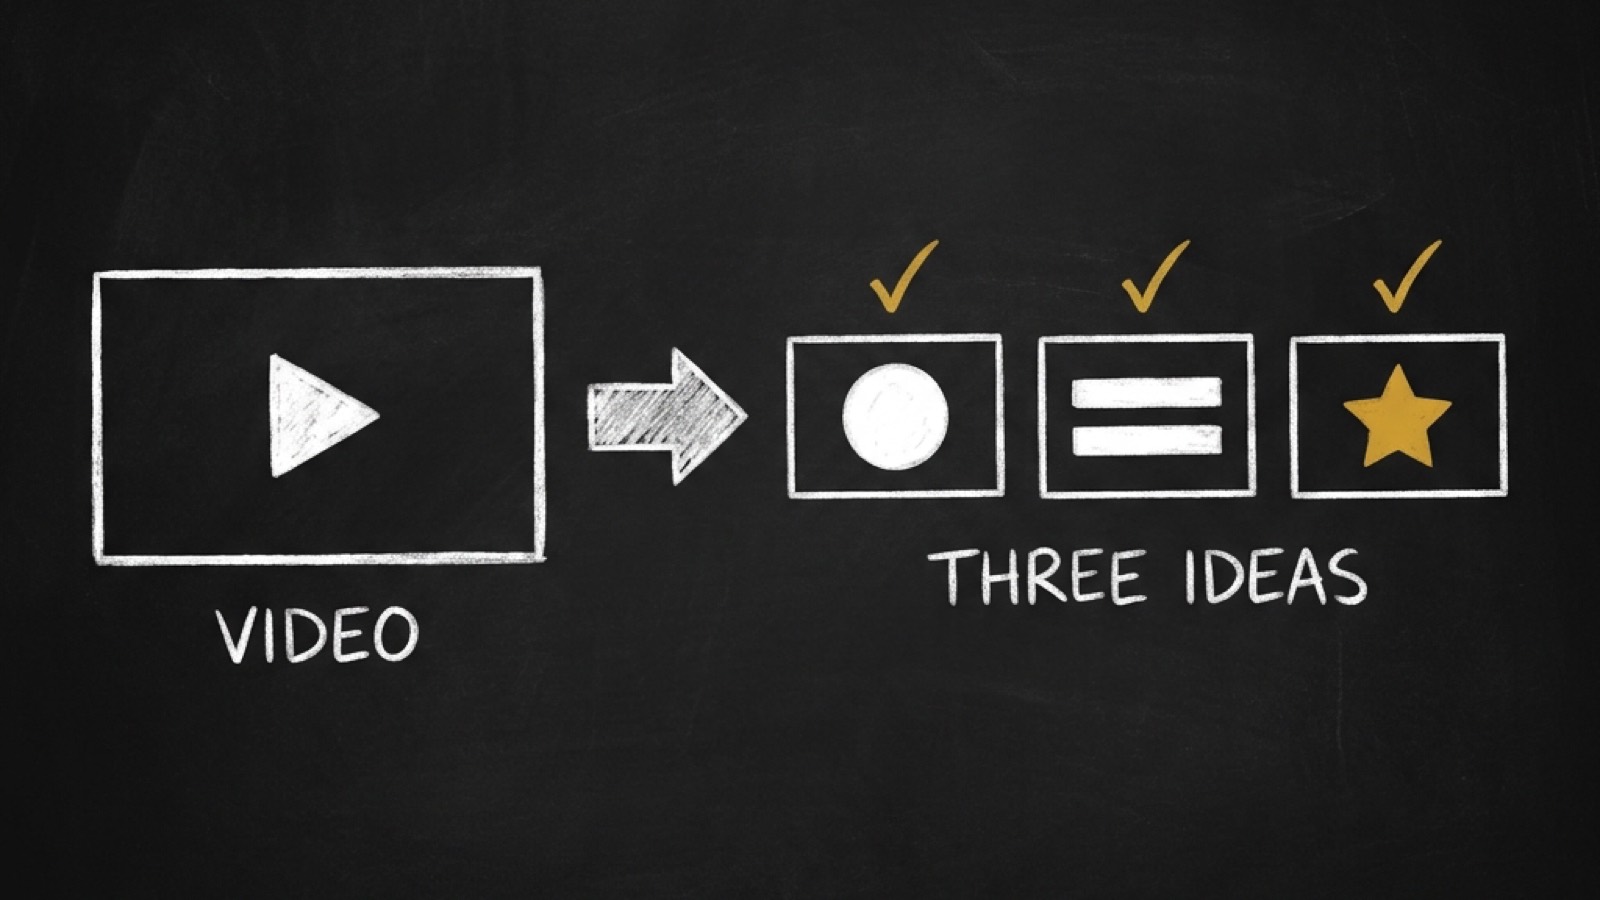
Give it a video and its title. It plans two or three thumbnails that test different ideas, grades each one where YouTube shows it smallest, and picks the frame your video should open on. Every check prints a number, so you see why an image passed or failed.
For founders and marketers who publish on YouTube, and who have run a thumbnail test that came back with no winner.
opvs-skills install @di-atomic/thumbnail --to ./skills-cacheUse --to, not --runtime: the scripts are the skill. Then say: “make 3 thumbnails to A/B test for this video” or “make a cover for this Short”.
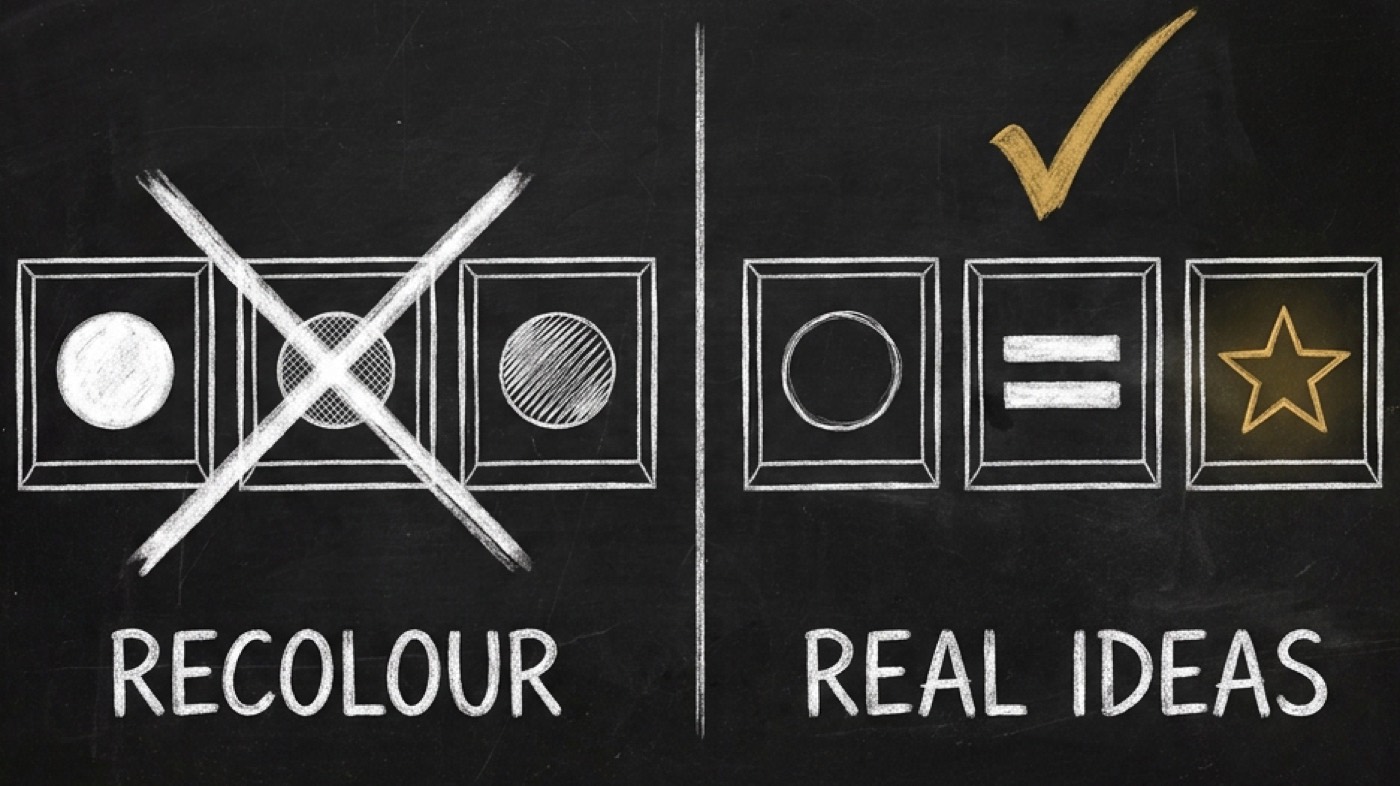
Why three shades of one thumbnail is not an A/B test
A  photo + "SWITCH TO CLAUDE"   blue
B  photo + "SWITCH TO CLAUDE"   orange
C  photo + "SWITCH TO CLAUDE"   green

→ same layout, same idea
→ fingerprint distance 0 to 1
→ readable at 200 px? never checked
→ no hypothesis to learn from

(YouTube: "no winner")
A recolour scores 0 to 1 against its original. Swapping only the words scores 0 to 12.
A  baseline       "SWITCH TO|CLAUDE"   left
B  promise        "CLAUDE|OR GPT?"     top
C  proof-object   "4 MINUTES|FLAT"     right

distance   A-B 27 · A-C 31 · B-C 40
size       18.8′ to 23.0′ at 200 px
contrast   21:1 on every headline
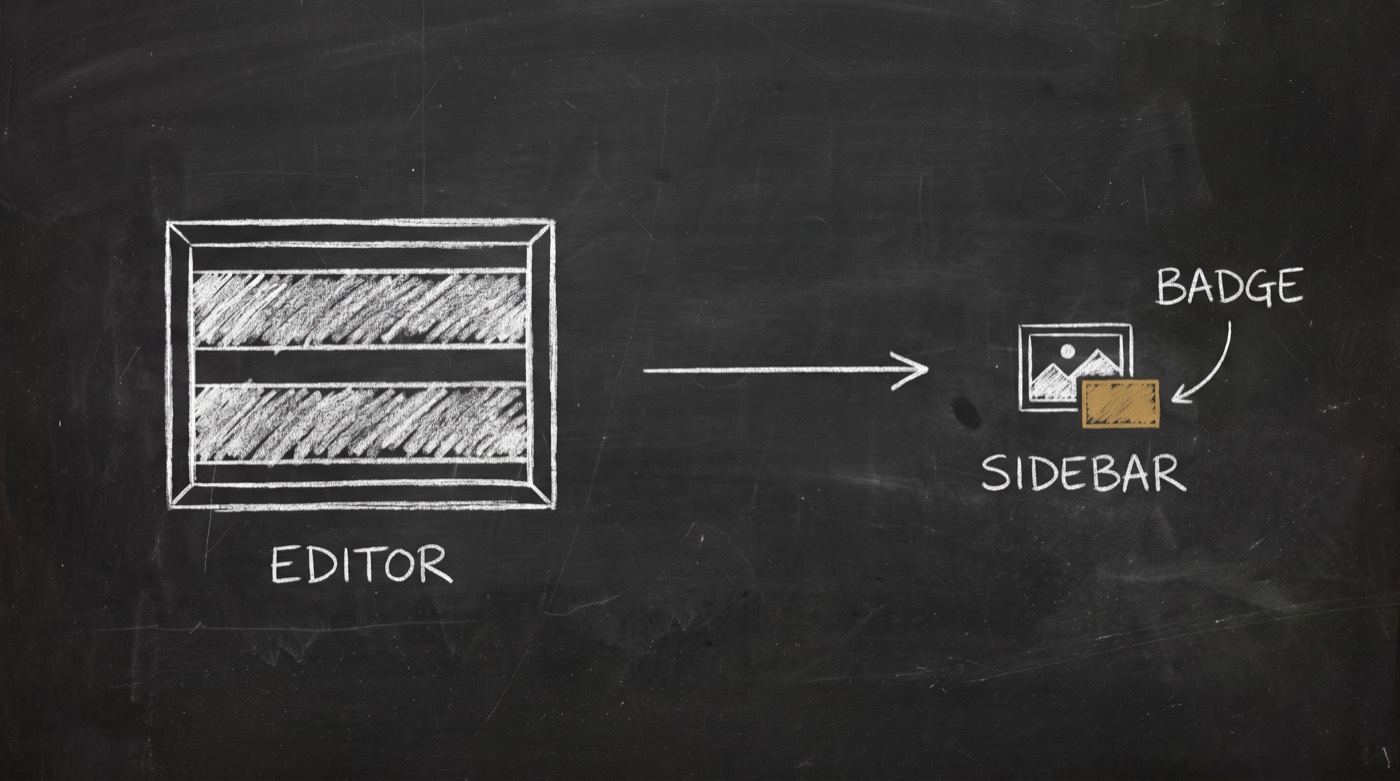
corners    nothing under the badge
A set I built on test backgrounds, graded by the skill's own scripts. Every pair clears 16.
Three versions of one idea teach you nothing. Three ideas show you what your audience watches.
Five scripts, and each one prints a number
compose-thumbnailTypesets the headline at the size the smallest display needs. Refuses a missing glyph, reversed Hebrew, or words that will not fit.verify-thumbnailGrades one image: headline height at 200 px, contrast, the badge corner and the Shorts overlays, and AI-drawn words read back.verify-variant-setChecks the A/B set: 2 to 3 variants, one named idea and one hypothesis each, every pair at distance 16 or more.pick-poster-frameProposes frames that are not black, not at a cut and settled, for video-editor to bake as frame 0.verify-coordinationConfirms the four OPVS surfaces are wired: the card, the docs, memory and the protocol.What you actually get
A YouTube A/B set
Two or three variants for Test and compare, each leading with one idea: promise, subject, proof object, emotion, or face against object. Each one carries a one-line hypothesis, so the result teaches you something.
Covers for Shorts, Reels, TikTok
One cover with the words kept where the platform leaves them visible. YouTube lays its Shorts title over 74% to 88% of the cover's height, so your words stay above it.
The right frame 0
A settled, non-black frame, picked from a contact sheet and handed to @di-atomic/video-editor, which bakes it in and reads frame 0 back to prove it.
A real set, a recolour, and a poster
> "make 3 thumbnails to A/B test for this video"   (test backgrounds, typeset headlines)

  verify-thumbnail A.jpg   PASS  "SWITCH TO CLAUDE"   19.0′ @200px · 21.00:1 · badge clear
  verify-thumbnail B.jpg   PASS  "CLAUDE OR GPT?"     23.0′ @200px · 21.00:1 · badge clear
  verify-thumbnail C.jpg   PASS  "4 MINUTES FLAT"     18.8′ @200px · 21.00:1 · badge clear

  verify-variant-set set.json
    V2 hypothesis   A=baseline · B=promise · C=proof-object
    V3 distinct     A-B 27 · A-C 31 · B-C 40          (every pair >= 16)
  RESULT ............... PASS

> a set of A and a recolour of A

  verify-variant-set set-recolour.json
    V3 distinct     A-A2 0                              FAIL
    V4 hygiene      A2 text vs ground 3.67:1            FAIL
  RESULT ............... FAIL

> "pick the poster for this clip"   (4 s, fades in from black, cut at 2 s)

  pick-poster-frame clip.mp4
    frame 0 today   black 100%
    candidates      3 of 40 frames (black 2 · at a cut 4 · unsettled 5)
  RESULT ............... PASS
Output I re-ran from the published bundle on test backgrounds I generated with ffmpeg, condensed to the lines that matter. No face and no AI render here: that path is the one untested part of this release.
What the gates see that your editor hides
What it will tell you it cannot do
- AI-drawn words are new. The render-then-read-back path has not run end to end on a real render yet. The read-back gate is tested, and typeset headlines are exact.
- It grades readability, not clicks. In 941 niche thumbnails, layout did not separate the videos that broke out. The gates keep images readable; the test finds the winner.
- I hold no click data of my own yet. Every finished test is written to your agent's memory, so your own evidence builds with each one.
- Cyrillic and Hebrew are typeset. OCR read-back is unreliable for Cyrillic and absent for Hebrew, so those headlines are set as type, never trusted to the AI.
- TikTok's grid size is an estimate. TikTok served a CAPTCHA to the measuring browser. The YouTube and Instagram sizes were measured.
- You bring ffmpeg and your photos. The scripts run on node and ffmpeg. The face library ships empty, and you add your own photos.
I wanted every video to get a fair test, not three shades of one guess.
thumbnail is one skill in the system behind Di-Atomic, the marketing and compliance agency that runs cognitoAI, SpiderIQ and OPVS. If you want a video pipeline that researches, scripts, edits and packages each video, in any of my team's seven languages, that is the day job.
Book a call with Di-AtomicJust want the skill? Get @di-atomic/thumbnail free.