Stop guessing your next video.
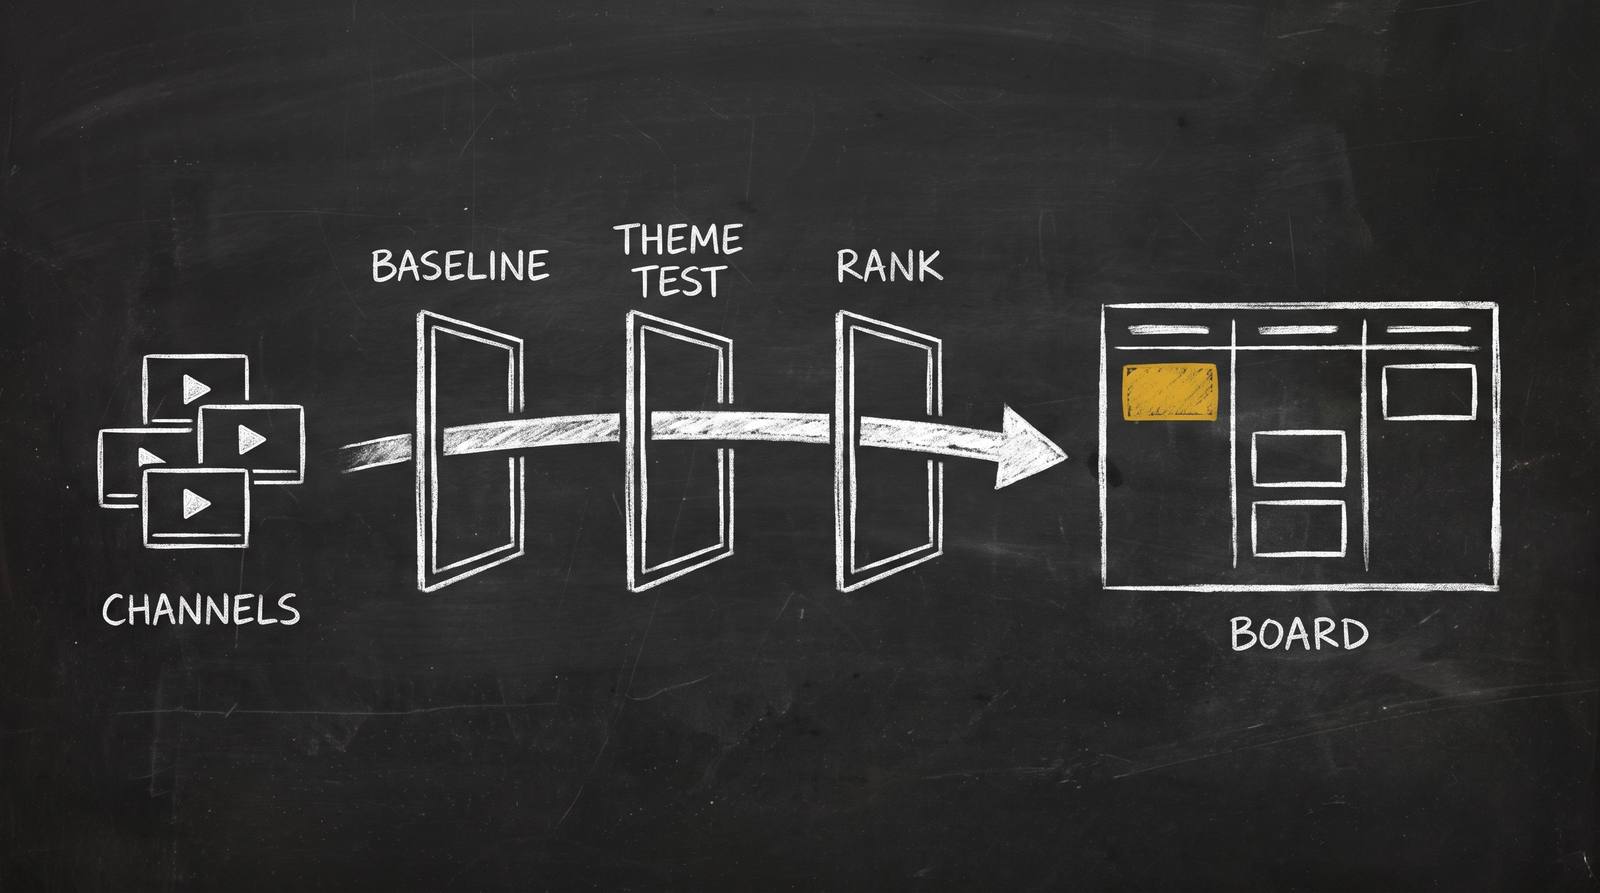
Every Monday your agent scores the channels you watch against their own baseline, tests each theme against the rest of their videos, and drops ranked video ideas on a board you pick from. Before anyone writes a tutorial, it reads the product's released code, so the script says what the tool really does.
For founders and marketers who make video for a business, and who have copied a trend that turned out to be one creator's habit.
opvs-skills install @di-atomic/video-researcherThen say: “run the weekly video scan” or “read the repo before we script it”.
Why a top-10 list sends you the wrong way
sort by views, or views over the channel mean
take the top 10, call the themes trends

→ big channels win on size alone
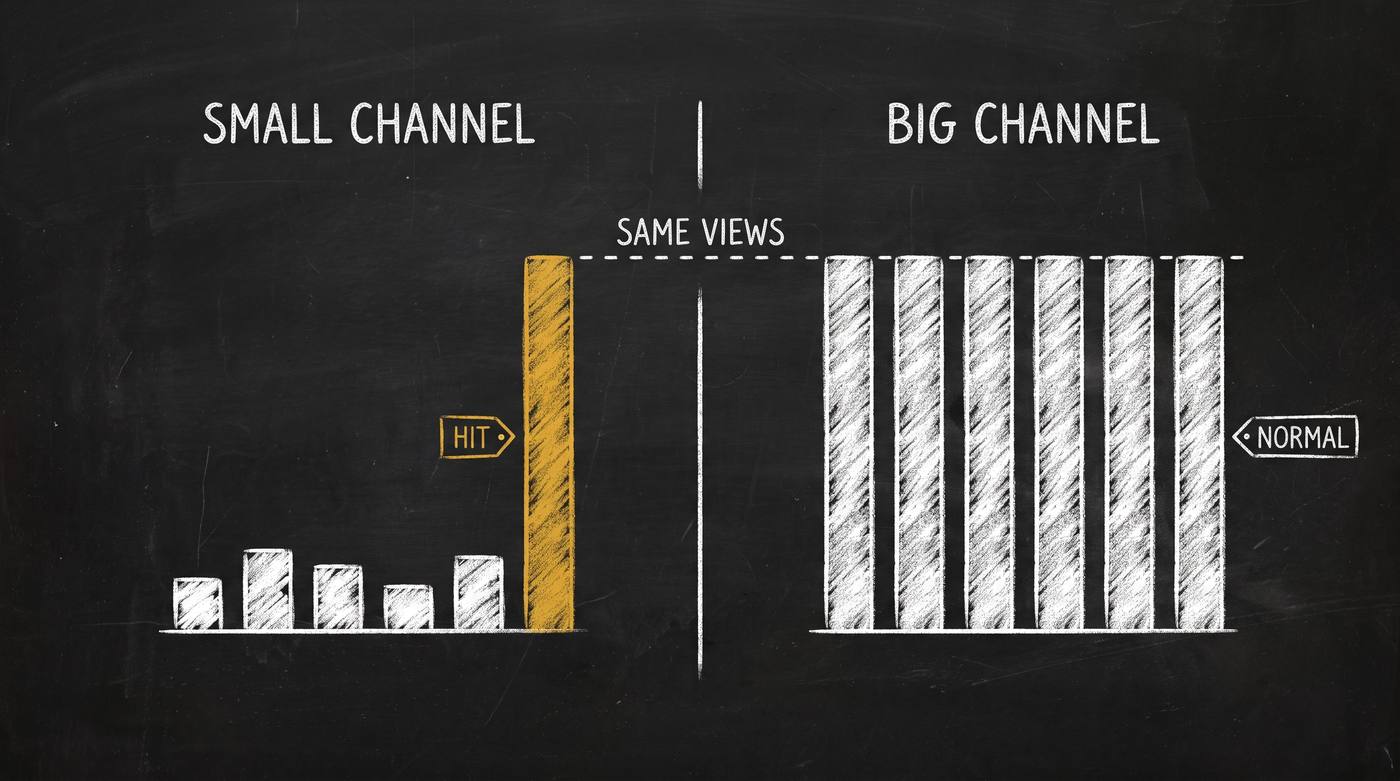
→ a mean baseline halves hit-driven ratios
→ "1 year ago" read as 364 days
→ one prolific channel becomes a trend
→ a sponsor flag read as a paid boost
→ a hook gets credit with no control

(it looks convincing, so nobody checks)
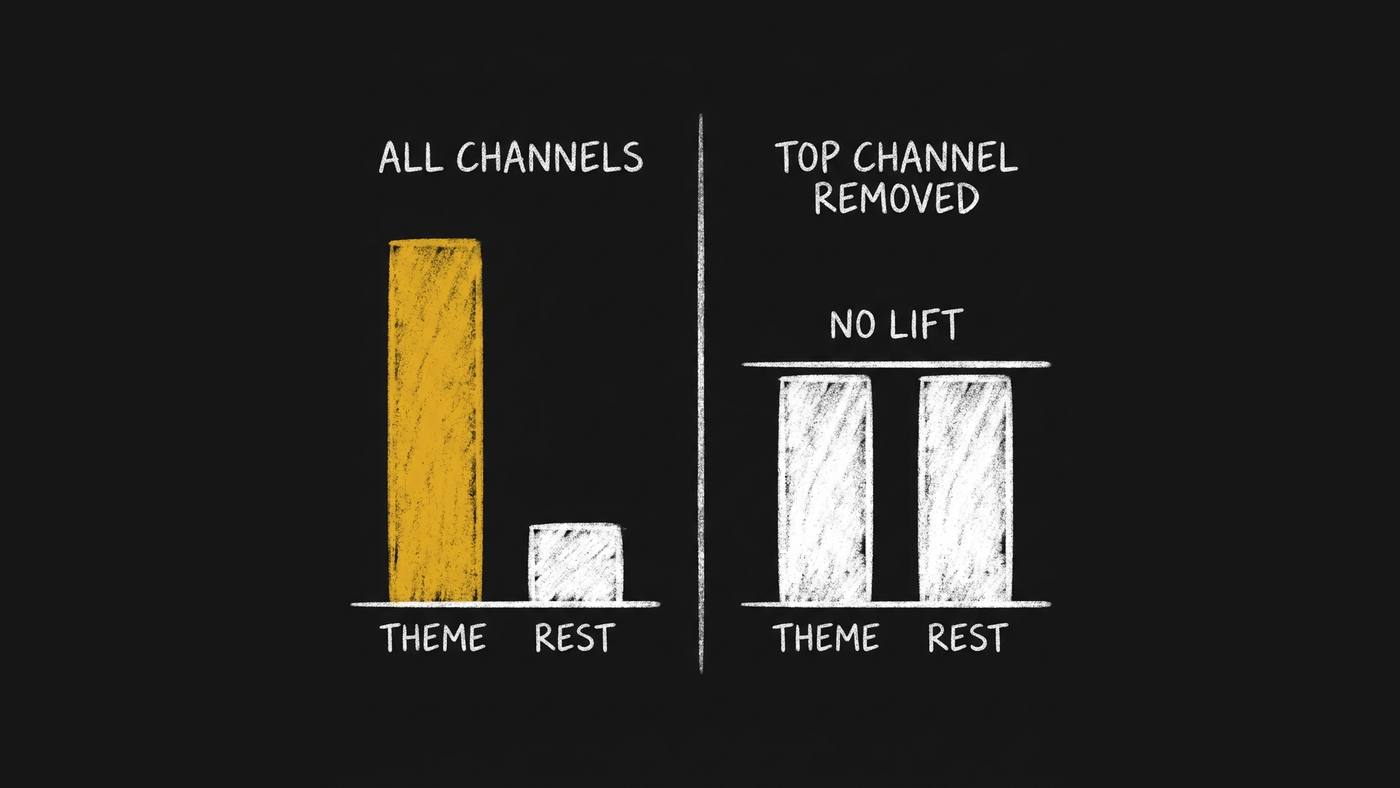
On the first real scan this list said web design. The whole effect was one channel that made 41 of the 58 videos.
watch set  declared per language
baseline   median, same channel, same format,
           same age band, 8 videos or more
outlier    3x or more, Shorts kept separate
theme      lift vs the rest, then again
           without its top channel
card       video, ratio, measured_at, class
board      Picked is yours, nothing moves
product    every claim at path:line@ref
An idea card you can check in a minute, because every number on it points at a video and the day it was measured.
A top-10 list is not evidence.
Five checks, and each one prints a number
verify-outlier-evidenceBlocks a ratio without a valid baseline, an age, a source or an evidence class. The mistakes from my own research fail it 9 times.verify-theme-liftBlocks a HIGH idea that fails lift, the top-channel test, breadth or sample size. The naive top-10 fails it twice.verify-claim-traceBlocks a claim without a live file and line, or one read from an unreleased version. A docs-and-latest-commit read fails it 8 times.lint-secretsBlocks a credential, an internal host, an email or a skipped file in anything handed to a writer. It has to print 0.run_keyLanguage plus ISO week. A second run in the same week makes 0 new cards and says so on the watch card.What you actually get
Scored against the channel itself
300,000 views is a hit on a channel that usually gets 40,000 and a normal week on one that gets 300,000. Each video is compared with the median of its own channel, in the same format and age band. A mean baseline halves the ratios on hit-driven channels, so it is never used.
Ideas on a board you own
A Research board with six columns: Watch, Ideas, Picked, Product reads, Handed off, Parked. Picked is yours. Ideas you skip for 21 days move to Parked, and next week's run reads what you ignored, so it learns your taste.
Scripts that match the code
Mode 2 reads the version people can install, not the latest commit. Its first read contradicted my own docs about Codex support (dist/cli.js:460 in @opvs-ai/skills@0.7.1). Each claim comes back confirmed, contradicted or not found, with a file and a line.
One week of data, two rankings
> "run the weekly video scan"   (EN watch set, 6 channels, 2026-W39)

  THE NAIVE TOP-10, graded by hand
  verify-theme-lift.mjs theme-lift.FAIL-naive-top10.json
    videos 221 · channels 6 · base outlier rate 9.0%
    T1 AI web design, priced  lift 2.81  robust 0.99 (-its top channel)  breadth 1
    ✗ "Web design is the #1 theme"
        graded HIGH but robust lift 0.99<1.5 · breadth 1<2
    ✗ "Claude Code for non-coders is hot"
        lift 0.59 < 1.0, belongs on the avoid list
  RESULT ............... FAIL, 2 violations

  THE SAME DATA, ranked by the skill
  verify-theme-lift.mjs theme-lift.real-2026-09-24.json
    T3 build & sell AI agents  n=47  17.0% vs 6.9%  lift 2.47  robust 1.68  breadth 3  → high
    T4 long course, 90 min+     n=4                  lift 6.03               breadth 2  → low
    T1 AI web design, priced    n=58  17.2% vs 6.1%  lift 2.81  robust 0.99  breadth 1  → low
  RESULT ............... PASS, 0 violations
Both runs are the script's own output on the shipped test data, condensed to the lines that matter, with channel handles replaced by their role. Same videos, same week: the hand-made list fails, and the skill's ranking passes.
Two ways a ranking lies
What it will tell you it cannot do
- It decides; it does not scrape or write. Mode 1 uses your own scrapecreators access, Mode 2 reads a repository you can already open. Without access it says so and stops.
- YouTube only in this version. English, German and Danish watch sets, each with its own baseline.
- Paid distribution is invisible. No public field shows whether ads pushed a video, so it never guesses. A sponsor flag is recorded as sponsor_disclosed, never as a boost.
- Small markets are noisy. Most Danish channels sit under a 500-view band median, so their ratios are marked low-confidence by default.
- Market evidence, not your audience. Until your own channel is in the watch set, fit to your product is a judgement, and the card says so.
- The theme thresholds are judgement. Set on one real scan and recalibrated after four weekly runs. Every card shows its confidence.
I wanted to film what works, not what one channel repeats.
video-researcher is one skill in the system behind Di-Atomic, the marketing and compliance agency that runs cognitoAI, SpiderIQ and OPVS. If you want a video pipeline that researches, scripts and checks its own output, in any of my team's seven languages and including regulated categories, that is the day job.
Book a call with Di-AtomicJust want the skill? Get @di-atomic/video-researcher free.