- Name
-
@di-atomic/video-editor
- Tagline
-
One finished video from a shot list, with the numbers that prove it is the video you planned.
- Hero subhead
-
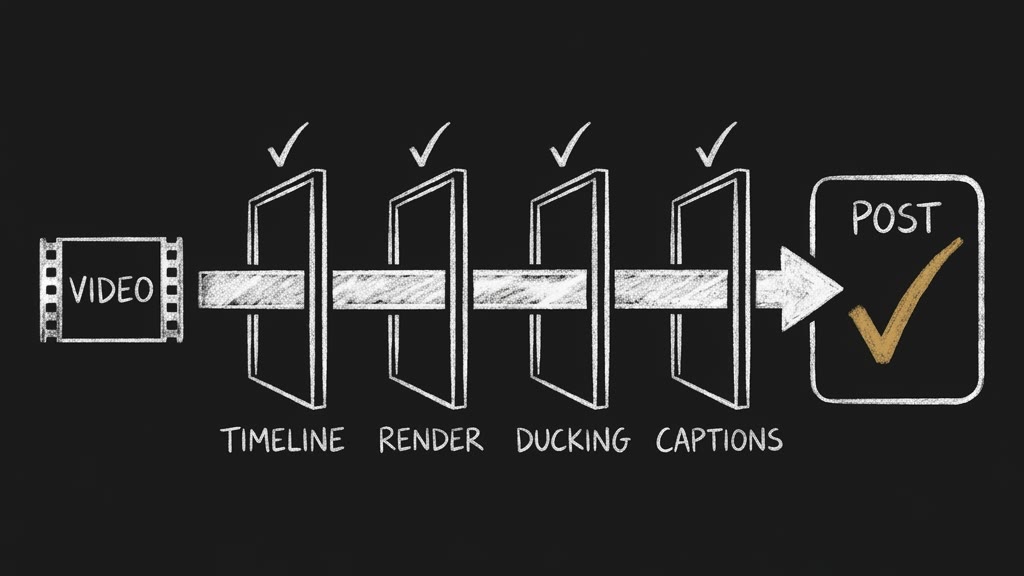
ffmpeg exits 0 when it writes a file, not when the file is right. This assembles a shot list and its finished assets into one video, renders it with local ffmpeg or hands it to SpiderVideo, and gates the finished file on timeline, render, ducking and captions.
- Who it's for
-
Anyone whose agent assembles video, and who has posted a render that finished cleanly and was still wrong.
- Version
-
0.1.0
- Tier
-
beta
- Path type
-
guidance-only
- Install command
-
opvs-skills install @di-atomic/video-editor
- Trigger phrase
-
cut the clips and the voiceover into one video
- Marketplace URL
-
https://market.opvs.ai/v/di-atomic/video-editor
- Blog URL
-
https://di-atomic.com/blog/shipping-di-atomic-video-editor
- Stat 1 value
-
9.96 dB
- Stat 1 label
-
the gap a mix-level ducking check reads on a video with no ducking
- Stat 2 value
-
0.01 dB
- Stat 2 label
-
how close the stem-share gate lands to the exact answer
- Stat 3 value
-
46 of 46
- Stat 3 label
-
controls fail for their stated reason, on macOS and on Linux
- Stat 4 value
-
4
- Stat 4 label
-
gates that read the finished file and print PASS or FAIL with numbers
- What headline
-
What you actually get
- Cap 1 icon
-
🎚️
- Cap 1 title
-
Ducking you can prove
- Cap 1 desc
-
The voice is in the mix while it speaks, so the mix is louder during speech whether the music moved or not: a 9.96 dB gap on a render with no ducking. The gate solves out = a*voice + b*music every 50 ms against the two tracks that went in, and also measures pumping between words.
- Cap 2 icon
-
💬
- Cap 2 title
-
Captions checked in pixels
- Cap 2 desc
-
Two moments of one video always differ, so the quick test passes a video with no captions at all. The editor compares the same frame with and without captions, and checks the font file covers every character before it renders.
- Cap 3 icon
-
🖥️
- Cap 3 title
-
Runs where your agent runs
- Cap 3 desc
-
In Claude Code, Codex or Antigravity it renders with the local ffmpeg from a graph computed off the shot list. On an OPVS agent with no ffmpeg it writes the SpiderVideo job and prints every field that path cannot honour. It complements SpiderVideo; it does not replace it.
- Showcase headline
-
Two tests that pass when they should fail
- Showcase before caption
-
A speech-versus-pause check on the mix finds a gap even when the music never moved, because the voice is part of the mix.
- Showcase after caption
-
Two timestamps always differ; the same frame with and without captions only differs where the captions are.
- Worked title
-
One 13-second render, gated
- Worked example
-
verify-timeline ...... FAIL
vo_inside_picture speech ends 12.69 s / picture 11.00 s
captions_inside_picture 6 words lost: "checked the mix before it shipped."
corrected plan ....... sum len 14 - overlap 1.00 = 13.00 s
verify-render ........ PASS h264 High 1080x1920 30 fps 13.000 s, -14.1 LUFS, TP -1.7
verify-ducking ....... PASS depth 12.02, balance 12.01, pump 0.43
verify-captions ...... PASS 31/31 words, 0.0000 % in pauses
- Worked framing
-
The first plan would have rendered with exit 0 and cut the last six words. The timeline gate refuses it before a single frame is encoded.
- Rel 1 icon
-
🎬
- Rel 1 name
-
@di-atomic/video-director
- Rel 1 desc
-
Writes the shot list this skill assembles.
- Rel 1 url
-
https://market.opvs.ai/v/di-atomic/video-director
- Rel 2 icon
-
🎨
- Rel 2 name
-
@di-atomic/media-generator
- Rel 2 desc
-
Renders the clips and the voiceover that fill it.
- Rel 2 url
-
https://market.opvs.ai/v/di-atomic/media-generator
- Rel 3 icon
-
🖊️
- Rel 3 name
-
@di-atomic/copy-engine
- Rel 3 desc
-
Writes the script the whole chain starts from.
- Rel 3 url
-
https://market.opvs.ai/v/di-atomic/copy-engine
- CTA headline
-
I wanted proof, not an exit code.
- CTA description
-
video-editor is one skill in the system behind Di-Atomic, the marketing and compliance agency that runs cognitoAI, SpiderIQ and OPVS. Guidance-only, so there is no backend to provision. Your agent runs the scripts in its own shell.
- Upstream license
-
MIT (ideas only, no upstream code ships)