- Name
-
@di-atomic/video-director
- Tagline
-
A shot list the renderer accepts unmodified, with arithmetic that does not ship black frames and voiceover lines that fit their shots.
- Hero subhead
-
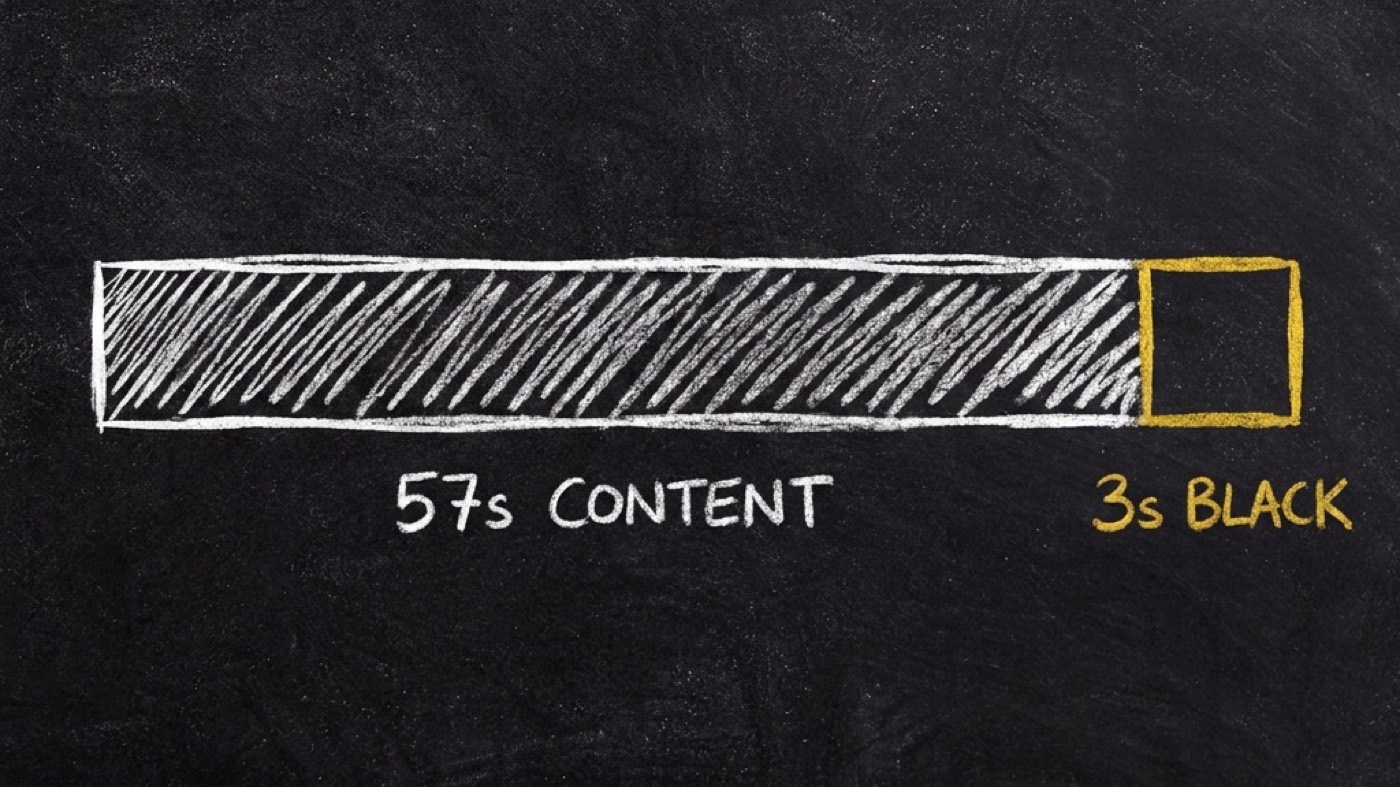
Transitions overlap their neighbours, so a plan summing to 60 seconds renders 57 seconds of content and 3 seconds of black. This solves for content instead of for the raw sum, quantizes generated clips to the lengths models actually produce, and times every voiceover line against the shot it plays over, from speech rates measured in 7 languages. It can also fill a template that video-analyst measured from a video you liked, and hand back what the engines cannot shoot.
- Who it's for
-
Anyone whose agent makes video, and who has watched a render succeed and still come back wrong.
- Version
-
0.3.0
- Tier
-
beta
- Path type
-
guidance-only
- Install command
-
opvs-skills install @di-atomic/video-director
- Trigger phrase
-
does this script fit 60 seconds
- Marketplace URL
-
https://market.opvs.ai/v/di-atomic/video-director
- Blog URL
-
https://di-atomic.com/blog/shipping-di-atomic-video-director
- Stat 1 value
-
3.0s
- Stat 1 label
-
of black a naive 60-second plan ships, measured on a real render
- Stat 2 value
-
11 of 35
- Stat 2 label
-
voiceover beats in my own 60-second demo scripts that ran past their shot
- Stat 3 value
-
12 of 12
- Stat 3 label
-
adversarial shot lists rejected, including an empty object
- Stat 4 value
-
5
- Stat 4 label
-
verifiers that print PASS or FAIL with numbers before a clip is bought
- What headline
-
What you actually get
- Cap 1 icon
-
🧮
- Cap 1 title
-
Arithmetic that accounts for overlap
- Cap 1 desc
-
Transitions overlap the shots either side of them, so content = sum(len) minus (n-1) times transition_seconds. Seven clips totalling 60 seconds with six half-second cuts render 57 seconds and 3 seconds of black. The planner solves for content, and the verifier prints the black tail you would have shipped.
- Cap 2 icon
-
🎛️
- Cap 2 title
-
Durations quantized to what models make
- Cap 2 desc
-
veo3 returns 8 seconds, sora2 returns 10 or 15, and no model honours a request for 6.3. Screen recordings and motion compositions are elastic and absorb the remainder, so hitting a target is a small search rather than a subtraction.
- Cap 3 icon
-
⏱️
- Cap 3 title
-
Every voiceover line timed
- Cap 3 desc
-
Every voiceover line is timed against its own shot, not the whole video, from speech rates measured for EN, DE, ES, FR, HE, RO and RU. A beat that does not fit goes back to the writer with the word count that does. --tts swaps the estimate for real timings.
- Showcase headline
-
Engine is how the asset is made; type is derived from it
- Showcase before caption
-
ai and avatar are generated, capped at 5 to 15 seconds and only on native lengths.
- Showcase after caption
-
screen is a real recording and motion is a composition. Both are any length, and both are where the slack goes.
- Worked title
-
A 60-second script that fits its total and fails 3 beats
- Worked example
-
verify-vo-fit.mjs demo-script.md lang en, rate 2.38 (measured, conservative)
0-5s Hook window 4.9s est 4.62s PASS
5-15s Setup window 9.9s est 11.76s FAIL +1.86s max_words 23
50-58s compliance window 7.9s est 10.08s FAIL +2.18s max_words 18
58-60s Close window 1.75s est 5.46s FAIL +3.71s max_words 4
measured total speech 55.1s of 60s (the total fits)
RESULT ........ FAIL (3 beats)
--tts with the real voice: 2 real overflows, the setup fits
verify-shot-list ......... PASS content 60.00s
verify-seam-ledger ....... PASS 0 defaulted transitions
- Worked framing
-
The total fit with five seconds to spare, and three beats still did not. Only those beats go back to the writer, each with the word count that fits, before anyone records a word.
- Rel 1 icon
-
🎨
- Rel 1 name
-
@di-atomic/media-generator
- Rel 1 desc
-
Renders the ai and avatar rows this skill plans.
- Rel 1 url
-
https://market.opvs.ai/v/di-atomic/media-generator
- Rel 2 icon
-
🔍
- Rel 2 name
-
@di-atomic/video-analyst
- Rel 2 desc
-
Measures a video you liked into the template this skill fills.
- Rel 2 url
-
https://market.opvs.ai/v/di-atomic/video-analyst
- Rel 3 icon
-
🖊️
- Rel 3 name
-
@di-atomic/copy-engine
- Rel 3 desc
-
Writes the script this skill turns into shots.
- Rel 3 url
-
https://market.opvs.ai/v/di-atomic/copy-engine
- CTA headline
-
I got tired of renders that succeeded and were still wrong.
- CTA description
-
video-director is one skill in the system behind Di-Atomic, the marketing and compliance agency that runs cognitoAI, SpiderIQ and OPVS. Guidance-only, so there is no backend to provision and nothing to wire up. It decides, composes and checks the clock; it renders nothing and writes no words, and it says so.
- Upstream license
-
MIT