- Name
-
@di-atomic/video-analyst
- Tagline
-
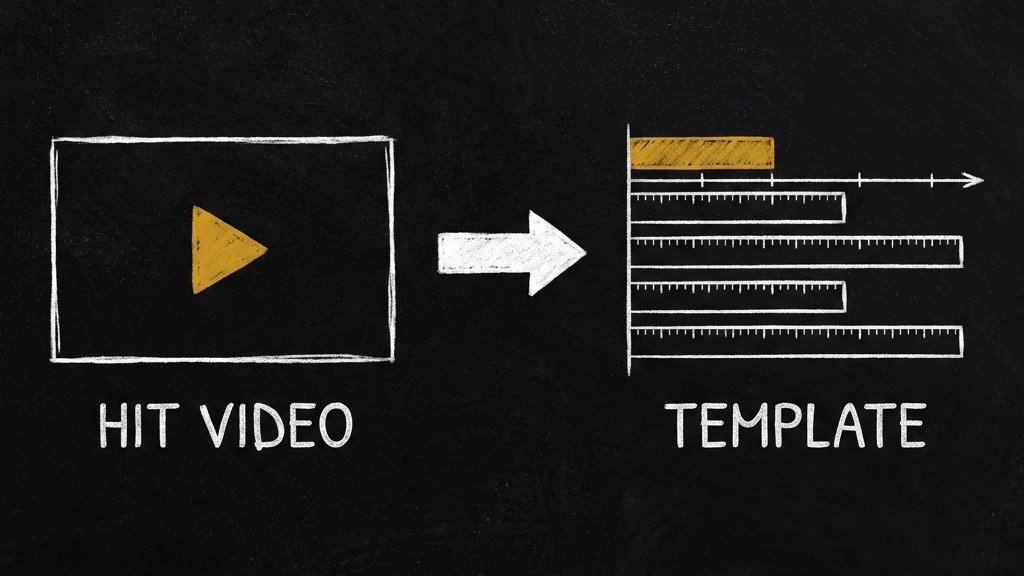
A YouTube link or a video file in, a reusable template out: timed sections, voice-over pace, opening rules and checked shot rhythm.
- Hero subhead
-
A summary tells you what a video said. A template tells you how it was built, in numbers your next video can use. Scripts measure timing, pace and cost; your agent's own model checks every cut from the frames around it and judges sections and hooks; every number says which of the two it came from.
- Who it's for
-
Founders and marketers who make video for a business, and who have copied a video's structure by eye and got the pacing wrong.
- Version
-
0.1.0
- Tier
-
beta
- Path type
-
guidance-only
- Install command
-
opvs-skills install @di-atomic/video-analyst --to ./skills-cache
- Trigger phrase
-
watch this video and make a template
- Marketplace URL
-
https://market.opvs.ai/v/di-atomic/video-analyst
- Blog URL
-
https://di-atomic.com/blog/shipping-di-atomic-video-analyst
- Stat 1 value
-
12
- Stat 1 label
-
timed sections pulled from Linear's 4-minute product intro
- Stat 2 value
-
12.4x
- Stat 2 label
-
longer shots in its demo than in its hook, so one average fits no part of it
- Stat 3 value
-
195
- Stat 3 label
-
median words per minute across 14 measured videos. Most plans assume 150.
- Stat 4 value
-
28,832
- Stat 4 label
-
image tokens for that full 4-minute run, cut checks included
- What headline
-
What you actually get
- Cap 1 icon
-
🎞️
- Cap 1 title
-
Link or file in, template out
- Cap 1 desc
-
Captions come first and cost nothing in image tokens. Frames are pulled only where a judgment needs eyes. Each video becomes one record; videos of one kind become one template your library keeps by name.
- Cap 2 icon
-
📏
- Cap 2 title
-
Every number labelled
- Cap 2 desc
-
Scripts measure timing, pace and cost. YouTube supplies views and the replay heatmap. Your agent's own model judges sections and hooks, and cites the frame it used. The label travels with the number.
- Cap 3 icon
-
🧮
- Cap 3 title
-
Strength follows sample size
- Cap 3 desc
-
One video is a hint. Six is the first sample where the range from lowest to highest covers the true median 96.9% of the time. Every opening rule says how many videos back it, like 5/6.
- Showcase headline
-
What a template sees that your eye misses
- Showcase before caption
-
One video, two speeds: Linear's hook cuts every 1.6 seconds while its demo shots hold for about 20, so one average describes neither.
- Showcase after caption
-
The template carries a director_input block in the exact shape video-director accepts, so a shot list starts from a proven structure.
- Worked title
-
A control video, then a real one
- Worked example
-
control: 40 s promo, 9 cuts known from its source
ffmpeg scene > 0.2 / 0.3 / 0.4 ..... 0 cuts each
detect-shots candidates 11, all 9 cuts on the right second
verify-cuts CONFIRMED TP 9 FP 0 FN 0 F1 1.00 mean |offset| 0 ms
Linear, Intro to Linear, 4:01
speech 649 words, 168.7 wpm, first word 0s
audit 83/83 candidates, 25 shot changes, precision 0.301
cost 6897 frames + 21935 sheets = 28832 image tokens
verify-template .... PASS, director_input 12 section timings
- Worked framing
-
The ffmpeg and detector lines were re-run on the control video that ships in the bundle; the verify-cuts line is from the build's control test, where the checking agent knew the answer. The Linear block is the scripts' own output on the bundled template.
- Rel 1 icon
-
🎬
- Rel 1 name
-
@di-atomic/video-director
- Rel 1 desc
-
Turns a script into a shot list. It fills the template's section timings.
- Rel 1 url
-
https://di-atomic.com/skills-video-director
- Rel 2 icon
-
🔭
- Rel 2 name
-
@di-atomic/video-researcher
- Rel 2 desc
-
Finds the videos worth studying. This skill studies them.
- Rel 2 url
-
https://di-atomic.com/skills-video-researcher
- Rel 3 icon
-
✂️
- Rel 3 name
-
@di-atomic/video-editor
- Rel 3 desc
-
Renders the shot list into one video and checks the result.
- Rel 3 url
-
https://di-atomic.com/skills-video-editor
- CTA headline
-
I wanted every video to start from a structure that already worked.
- CTA description
-
video-analyst is one skill in the system behind Di-Atomic, the marketing and compliance agency that runs cognitoAI, SpiderIQ and OPVS. Guidance-only, so there is no backend to provision. Your agent runs the scripts in its own shell and reads the frames with the model it already uses.
- Upstream license
-
MIT (frame and caption extractor adapted from claude-video; licence and change list ship in scripts/watch/)